Meme-Qwen-7B-Instruct
Language modeling · Jan. 2026
 Model
Meme-Qwen is an experiment in teaching a compact language model the timing, references, and conversational rhythm of Chinese internet memes rather than simply adding meme vocabulary to otherwise generic responses.
30,000+raw pairs collected
8,680released examples
+32%meme-use accuracy
Data-to-model pipeline
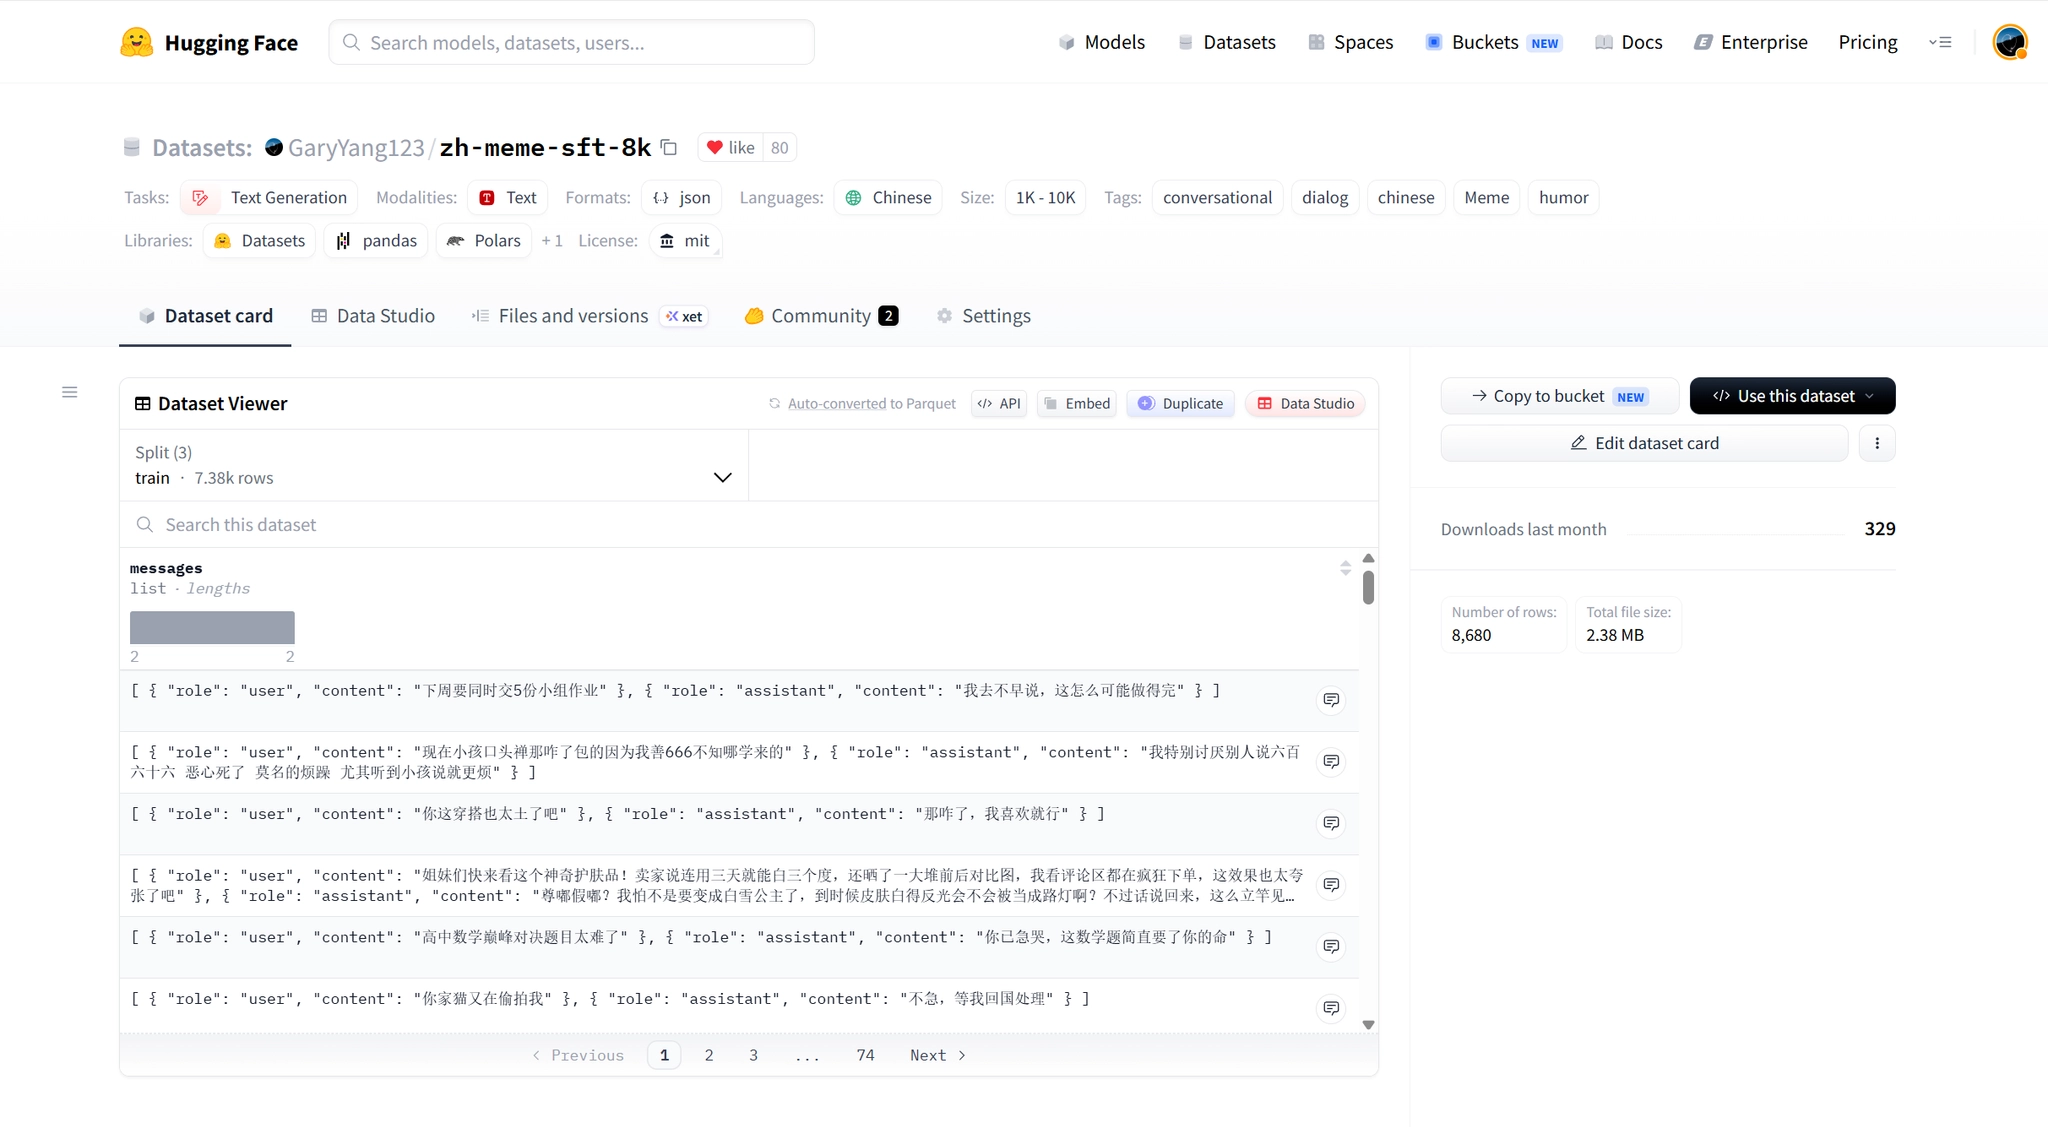
I collected public Chinese post-comment pairs with Playwright, filtered and normalized the data, and released the selected conversations in ChatML format. To our knowledge, it is the first open conversational SFT dataset and model centered on Chinese internet-meme usage.
Training and evaluation
Qwen2.5-7B was trained on a single A100 40GB GPU using LoRA followed by DPO preference alignment. Human and LLM preference evaluations reached 82%, 91%, and 68% for humor, meme accuracy, and conversational naturalness, respectively.
The objective was not to maximize meme frequency. It was to make references appear naturally, at the right moment, without overwhelming the conversation.